
2024 Product Innovation Recap
Apache Druid® is an open-source distributed database designed for real-time analytics at scale. Since our founding ten years ago, Imply has been committed to growing the Apache Druid project by making it as easy as possible for people to use Druid and build awesome data applications on top of it.
In 2022, we launched Imply Polaris: a hassle-free, fully managed cloud environment that serves as the “easy button” for Apache Druid. This database-as-a-service brings you all the performance advantages of Druid, plus add-in auto-scaling capabilities for seamless data ingestion, and an easy interface to build analytics applications to visualize your data in real time. Within minutes, you can derive valuable insights from all your data without the complexities of procuring and managing infrastructure.
We’ve made a lot of progress over the past decade. As we reflect upon the past year, we’re proud to share a summary of the top 2024 product updates across both Druid and Imply.
2024 in Numbers
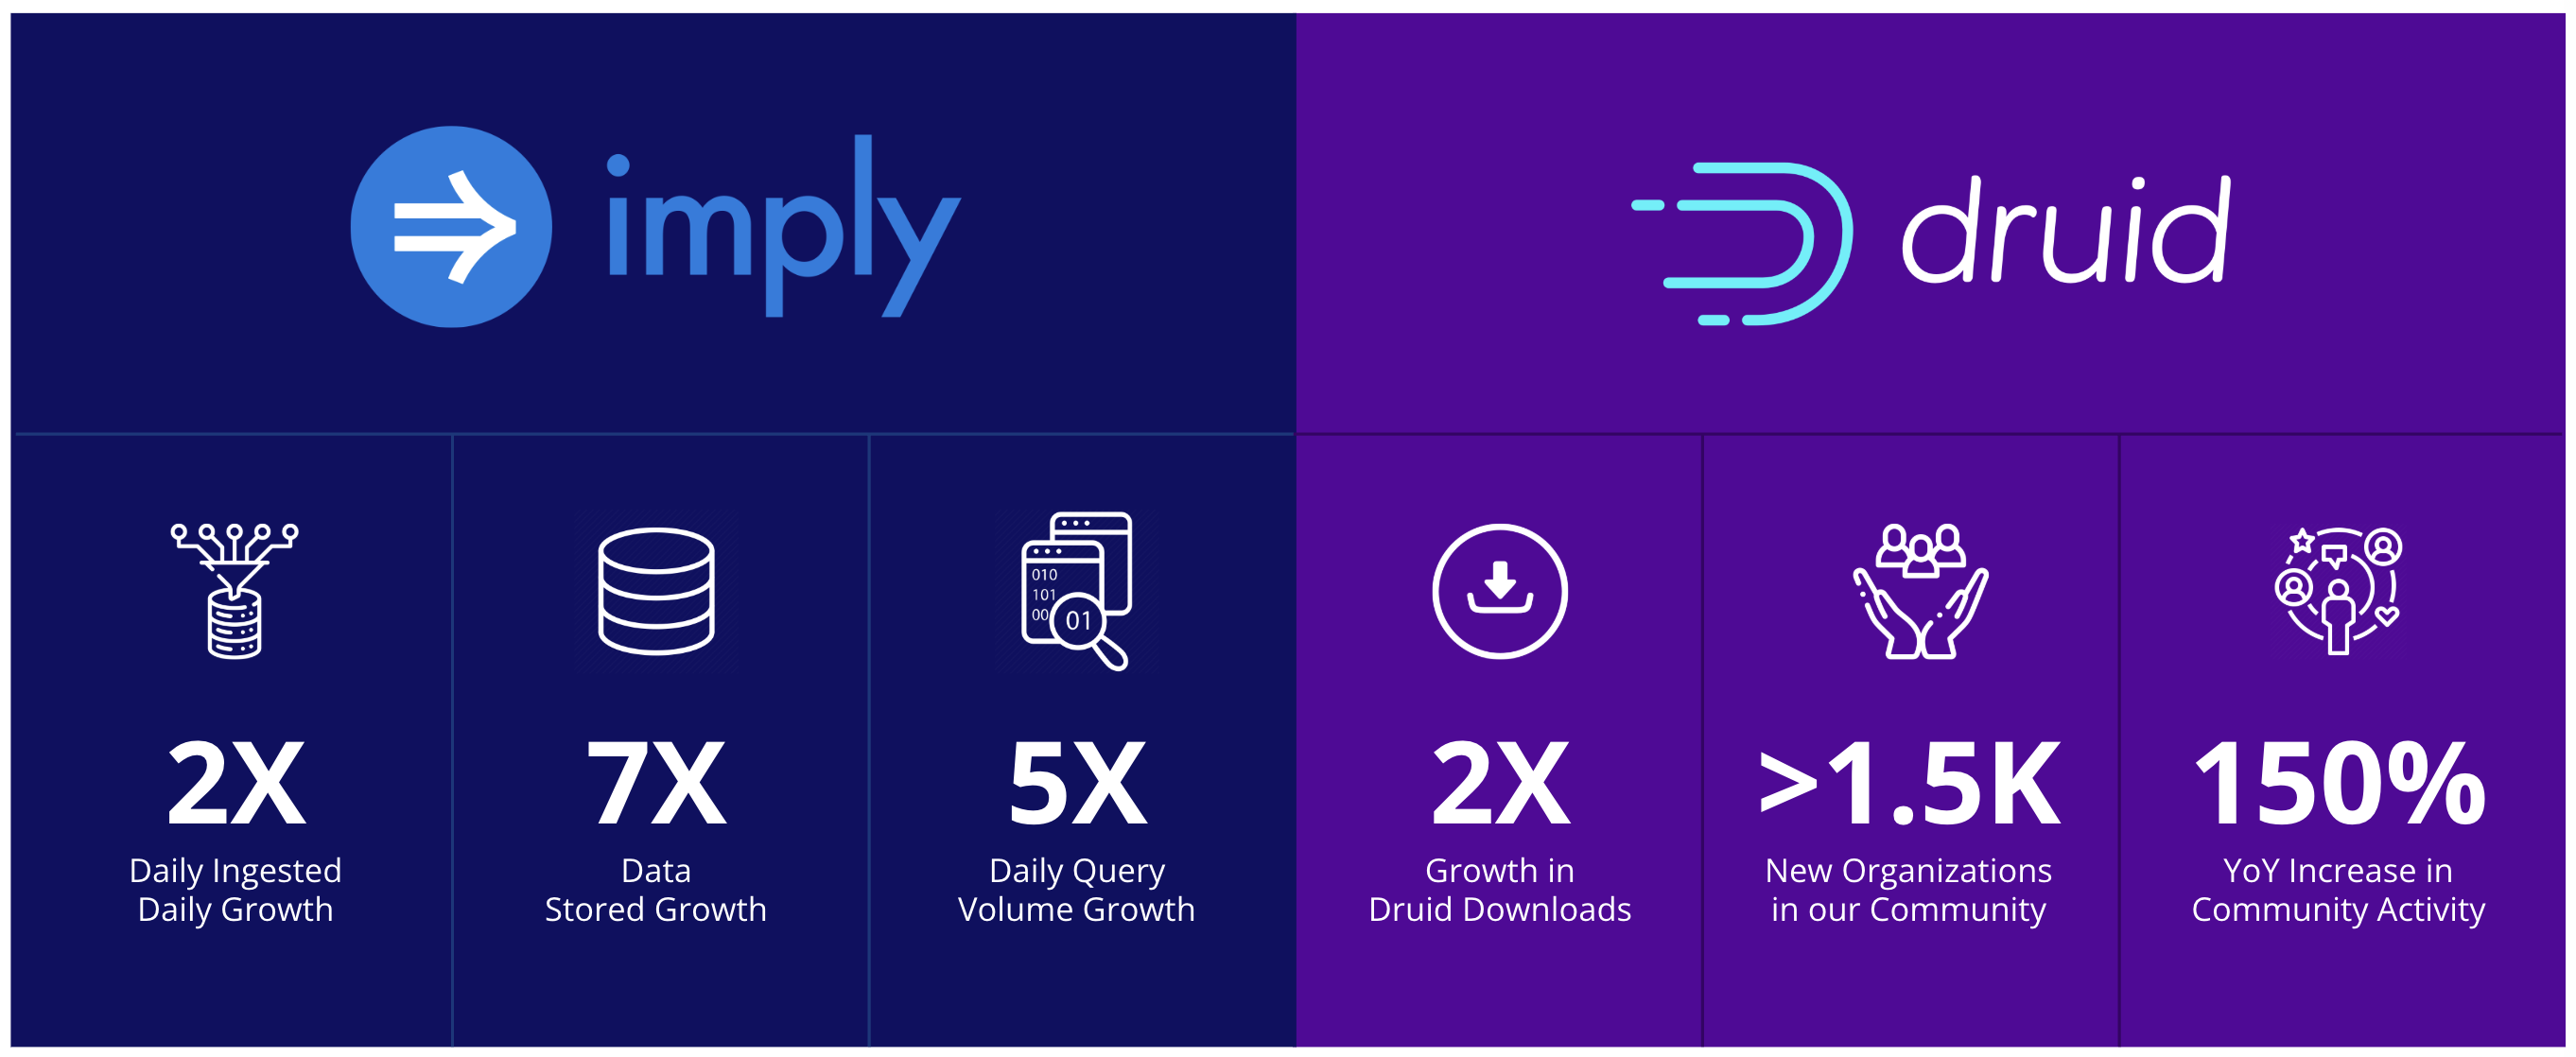
2024 was a banner year, totaling over 1,348 commits by 106 contributors across Apache Druid 29, 30, and 31. On top of this, we released 71 product updates, 124 other improvements, and 156 fixes to Imply Polaris.
Here’s a snapshot of 2024 growth across data usage and community activity overall:
2024 Product Innovation Strategy
While there are many ways to categorize our progress across features and functionalities, there were four main strategic pillars that guided our product innovation in 2024:
(1) ECOSYSTEM: Power Partner Connections & Seamless Data Ingestion
In our co-founder Eric Tschetter’s Druid Summit keynote, he introduced a new perspective on data solutions and infrastructure. The future lies in thinking about data in terms of entities (“things” like videos on Netflix or communities on Reddit) and events (“actions” like views or plays). Druid is focused on an events-first mindset. At its core, Druid provides a high-performance, ultra-low latency query engine that ingests events from streams and batch storage, transforms them by aggregating events and reconstructing entities, and then queries those events and entities for real-time and historical analysis.
To build upon this vision, expanding connections to more partners and data types is just one piece of the puzzle (e.g. expanded support for data lakes and Azure in 2024). Adding a data type is one thing, but making it so the data can be queried efficiently is a game changer. Our goal is to make ingestion as easy as possible, minimizing the workarounds to prepare your data for transformation and analysis (e.g. async query, dimension tables).
(2) ANALYTICS: Simplify Complex Queries with SQL Completeness
SQL is the standardized language most developers use when building applications, so we strive to improve ANSI SQL compatibility across all analytics powered by our query engine.
In addition to making significant enhancements to our SQL planner engine in 2024 (e.g. new window functions, larger joins), we also explored ways to simplify the steps to do complex data transformations and analysis, from reducing subqueries to enabling easier visualization (e.g. Imply Pivot enhancements and time series analysis for Imply Polaris).
(3) PERFORMANCE: Push Scale & Operational Efficiency Boundaries
Druid is optimized for running on clusters with thousands of nodes without having to worry about complexity around data synchronization, metadata management and data movement. Our goal is to push scale and operational efficiency boundaries to new limits.
While the aforementioned SQL planner improvements impact analytical efficiency, there are three main areas that we explored in 2024 to improve query engine performance while compacting storage from a system automation perspective: a new query engine called Dart, continuous defragmentation, and enhanced auto-scaling for Imply Polaris.
(4) PROTECTION: Enhance Resiliency, Security & Governance
The three strategic pillars above focus on the scope, functionality and efficiency of Druid’s query engine, with the majority of updates available in both Druid and Imply. That said, protecting the database itself is of equal importance. While OSS users have to manually implement Druid without the support of Imply’s managed service, they also have to construct entire systems to protect the resiliency, security and governance of the database.
Our fourth strategic pillar focuses exclusively on Imply Polaris, our fully managed database-as-a-service. With Polaris, we took advantage of all of the capabilities above, included all the Druid features, and added a whole layer of enterprise-grade security (private networking, role-based access control, audit logs, compliance), resiliency (fault tolerance, cluster self-healing), elasticity (scaling, no downtime, high availability) and operational efficiency (ZK monitoring UI, data deletion controls, no downtime or patching), deployed in multiple clouds and regions globally.

There are many technical details to explore within these updates, so we encourage you to dive deeper in our 2024 Product Updates: Technical Summary. This expansive Developer Center article fully defines the purpose and value of the top 2024 product updates shown in the image above, plus a few extra updates that didn’t make the top of the list.
Learn More: Full Update Summary
Conclusion: 2024 Summary & 2025 Vision Preview
Throughout 2024, we extended our commitment to provide better experiences for Imply and Druid users alike by supporting additional data types, making it easier and more cost effective to conduct complex analysis, improving performance for operational efficiency at scale, and enhancing data protection for better security, resilience, and governance.
While most of these updates are available in Druid OSS, Imply customers benefit from earlier access to updates, 24/7 professional support, enhanced auto-scaling, more robust security and resilience, and many more features summarized here. Many of our customers have found that the cost of Imply pays for itself, reducing the total cost of ownership (TCO) by 50% or more through time savings and reduced data storage.
So what’s next for 2025? As we continue to innovate across ecosystem, analytics, performance, and data protection functionalities, there are three standout projects to look out for in the coming year:
- Dart engine (GA), the new high-parallelism engine complementing Druid’s native engine, will continue to be tested and refined. As initial tests show a potential up to 2000% performance improvement for demanding queries, we’re excited to see how Dart’s continued development will make waves across the industry.
- A Virtual Storage Fabric will enable segment loading on-demand to unify storage across datalake, cloud, local, and in-memory storage. By decoupling the compute and storage layer, this allows independent scaling to simplify data management and enable smoother, more efficient data querying directly within Druid.
- Projections embed materialized views directly within Druid’s storage layer, allowing for up to 10x faster query speeds on pre-aggregating data without affecting existing workflows.
Whether you’re using Druid, Imply, or other analytics tools today, we hope you’ve found some inspiration from what we’ve been working on to reshape the real-time data space.
Additional Resources
- 2024 Deep Dive: 2024 Product Updates: Technical Summary
- 2024 Release Notes: Imply Polaris / Apache Druid 29-31
- Technical Docs: Imply Polaris / Apache Druid
- Recap Blog Posts: Druid 29 / Druid 30 / Druid 31
- Druid Summit: Opening Keynote (2024 Recap) / Closing Keynote (2025 Vision)
- Try Imply Polaris: Request a Demo / Free Trial (+$500 Free Credits!)
Related articles
More from Imply on the same topic.

Search your Splunk DDSS archive without restoring it
Security teams often keep logs long after they have aged out of their SIEM platform’s searchable window. The data is there for investigations or audits, but accessing the data for insights can be complicated.

Claude makes dashboards now, Lumi is ready for them
This week Anthropic launched Claude Dashboards in beta. You connect a data source, ask a question in plain language, and Claude writes the queries and builds the dashboard.

Lumi Lounge Recap: 3 Takeaways from Splunk .conf26
The Imply Lumi Lounge sat directly across the street from Splunk .conf26 and reached venue capacity on both days. Digital signs around the Colorado Convention Center pointed attendees our way with a simple message: “Federated search, done right. Full SPL. Less spend.”


Agents don’t query like your detections do
A security team of four has run a major SIEM since February. Nobody on the team writes SPL. Nobody opens the console or looks at the dashboards. Every question goes through an AI agent, which writes the query, runs it, reads the result, and answers in plain language.

Why You Shouldn’t Have to Delete Your VPC Flow Logs
When a security incident happens, investigators almost always start with the same questions: Which systems communicated? Where did the traffic originate? What changed before the incident? Was data exfiltrated? AWS VPC Flow Logs are often the fastest way to answer those questions.

Splunk Smartstore vs Lumi Loglake: Two Very Different Ways to Search Logs in Object Storage
One copies data back before it can be searched. The other queries it where it lives. Lumi Loglake lets Splunk teams query logs directly in object storage, including AWS S3, Delta Lake, Apache Iceberg, using standard SPL.

Supercharging Schema-On-Read: Logs in Object Storage Don’t Need a Data Catalog
Machine data architectures are rapidly changing. As telemetry volumes continue to grow and as costs rise, organizations are increasingly moving logs and other machine data into object stores such as AWS S3.

Imply Lumi Loglake vs Splunk Federated Search for S3
Teams are increasingly moving log data into AWS S3 to reduce costs and extend retention. Both Lumi Loglake and Splunk Federated Search to S3 help you query data in AWS S3 to lower costs, however the two technologies have several notable differences.

A First Look at Lumi Loglake: Query Logs Where They Live
TL;DR: Imply Lumi Loglake is a lakehouse (separated compute/storage) architecture for unstructured logs that reduces costs from 40% up to orders of magnitude on your hardware/AWS/Azure bill used to run your SIEM/observability products.

Imply Lumi Major Release Preview: Continuing the Journey Towards Decoupled Observability/SIEM
We are getting ready to introduce the next major expansion of Imply Lumi and the observability warehouse. When we introduced the industry’s first observability warehouse, the goal was clear: decouple the observability stack by separating storage, compute, and access.

Query Lumi from Grafana: Now in Private Preview
Observability has a silo problem. Today, we’re removing another one. Imply Lumi’s Grafana Loki integration is now in Private Preview.
