
A First Look at Lumi Loglake: Query Logs Where They Live


TL;DR: Imply Lumi Loglake is a lakehouse (separated compute/storage) architecture for unstructured logs that reduces costs from 40% up to orders of magnitude on your hardware/AWS/Azure bill used to run your SIEM/observability products.
At Databricks Data + AI Summit, we will showcase Imply Lumi Loglake, a major step forward towards a decoupled architecture for observability, SIEM, and machine data.
The idea is simple:
Point Lumi at your logs. Start querying.
Fully separated compute and storage for unstructured logs.
No data pre-processing or pipelines to build upfront.
No rigid schemas to define before data becomes usable.
No need to move or duplicate data before you can work with it.
With Loglake, Lumi can query unstructured logs directly where they already live, including logs stored in AWS S3, Delta Lake, Apache Iceberg, and other open storage environments. Best of all, your existing tools and workflows continue to work no matter where the data lives.
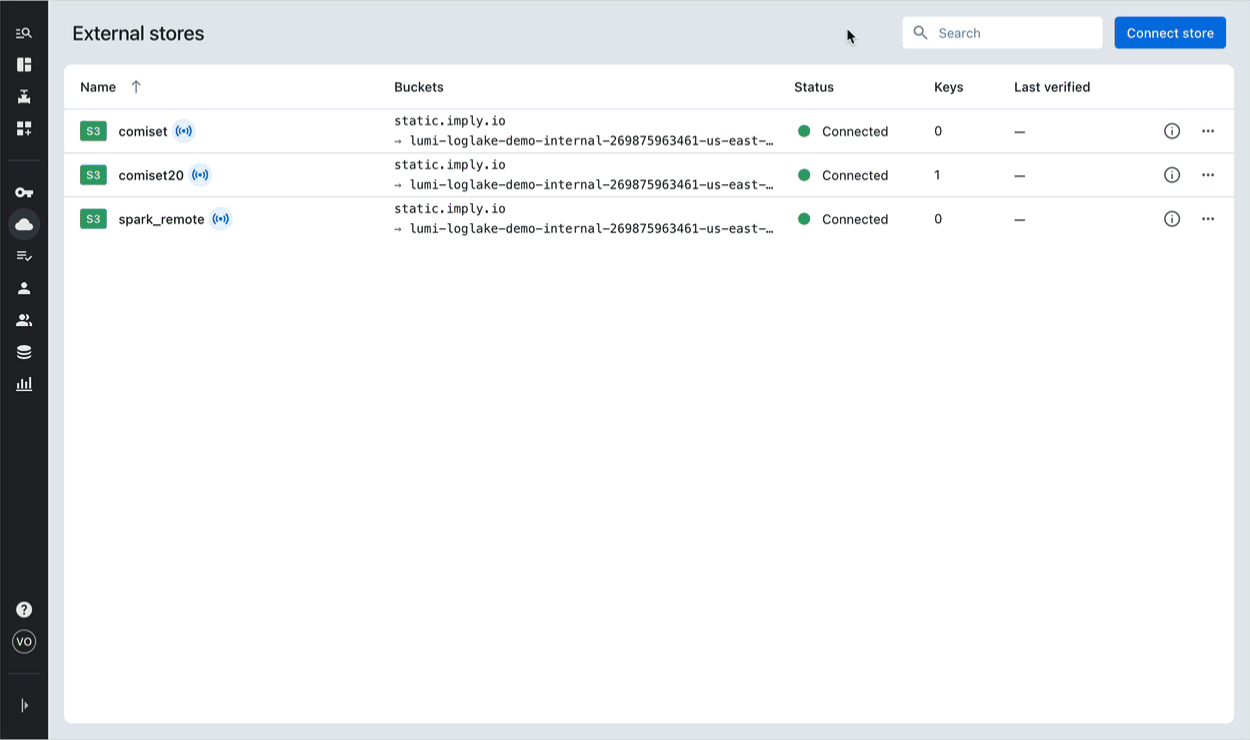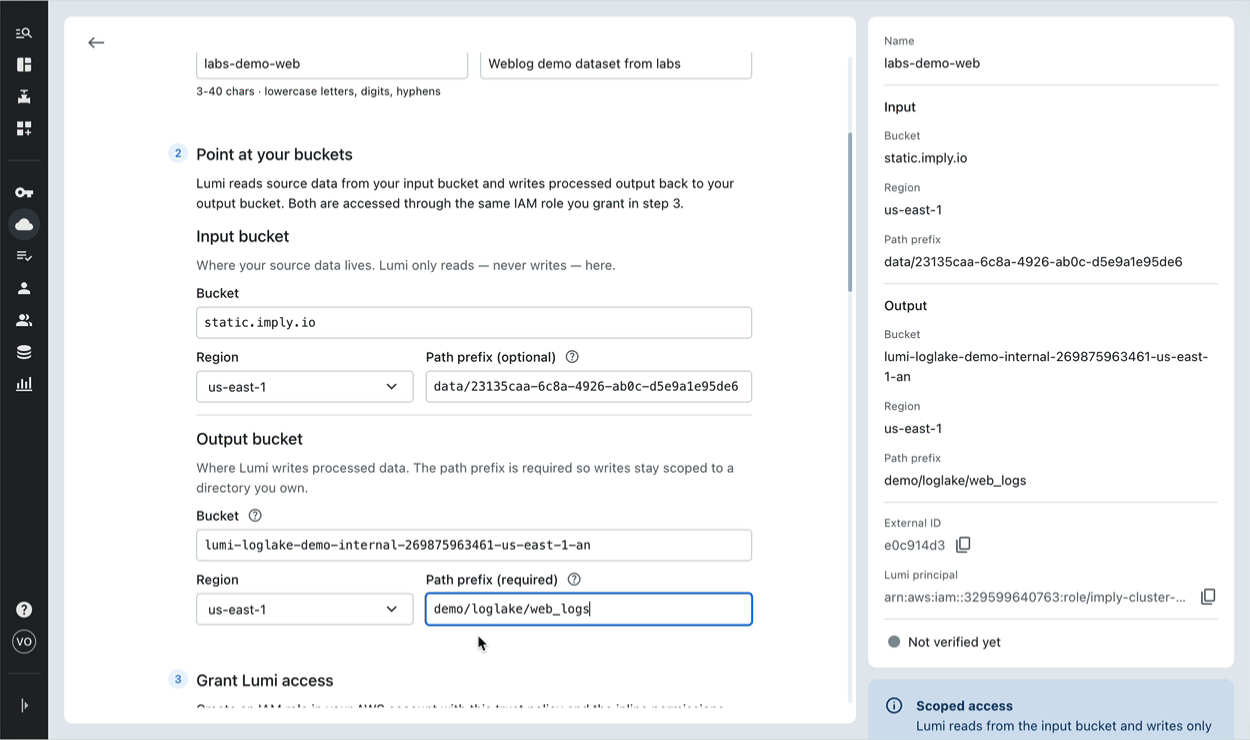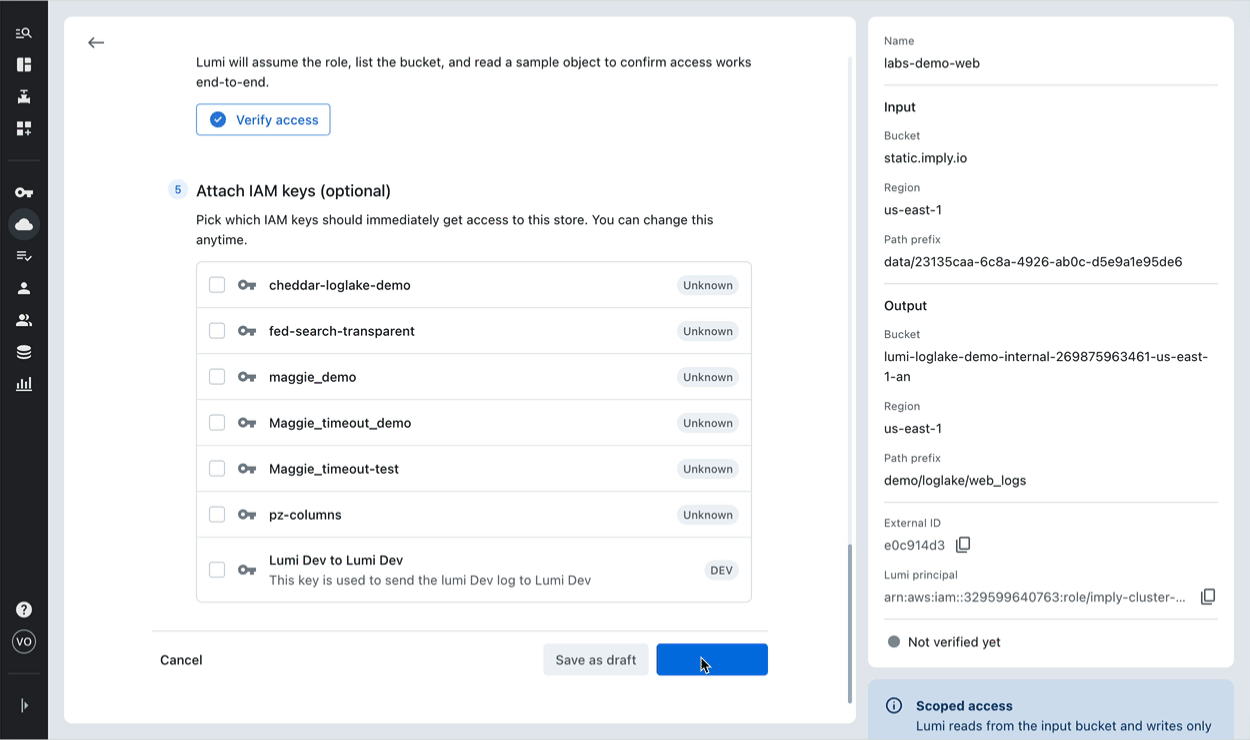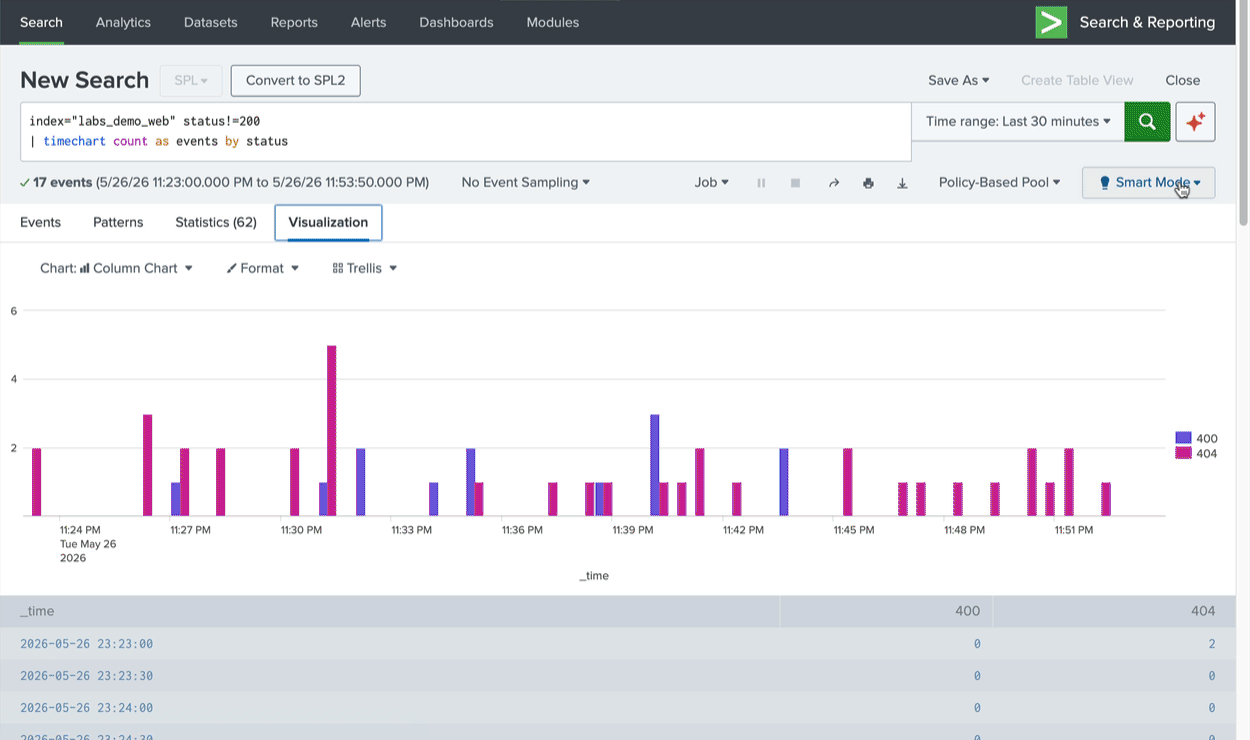
Loglake enables your Splunk UI and apps such as Enterprise Security to directly query logs in object storage. There’s no need to structure logs or pre-define schemas. Loglake leverages ephemeral compute that exactly matches your workload, reducing or bypassing the need for always-on compute, reducing your hardware costs.
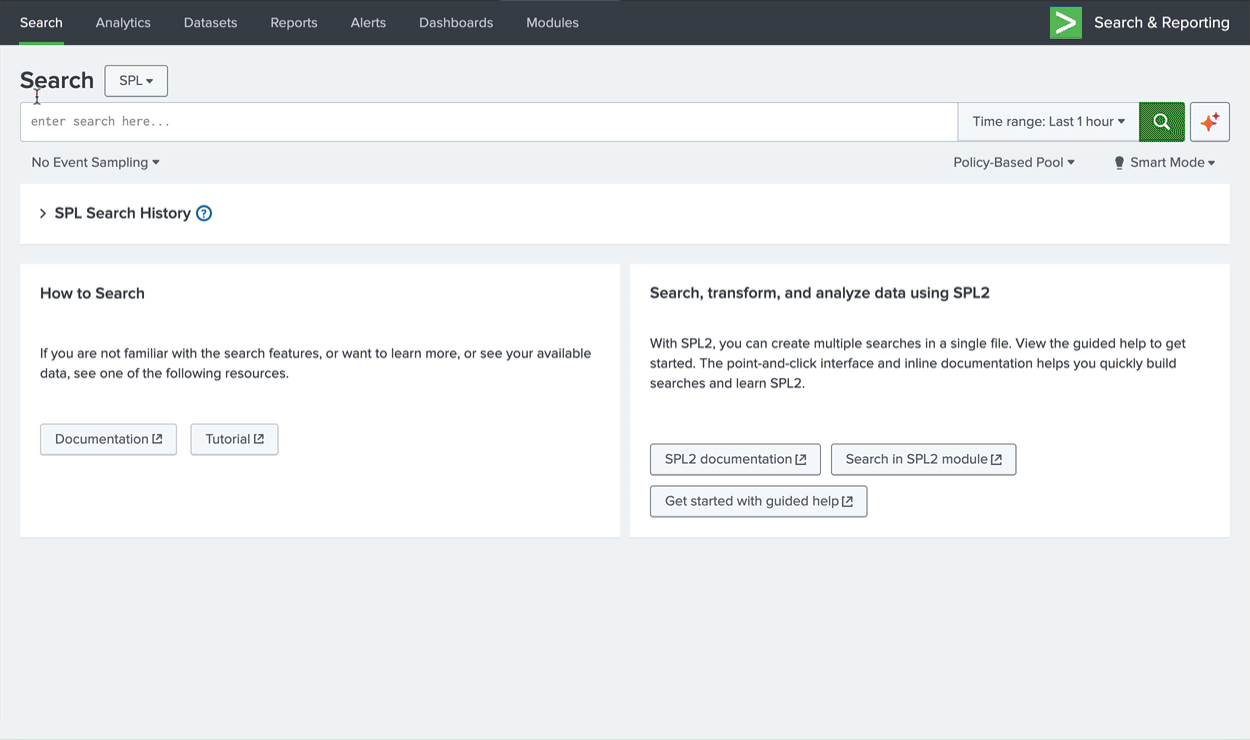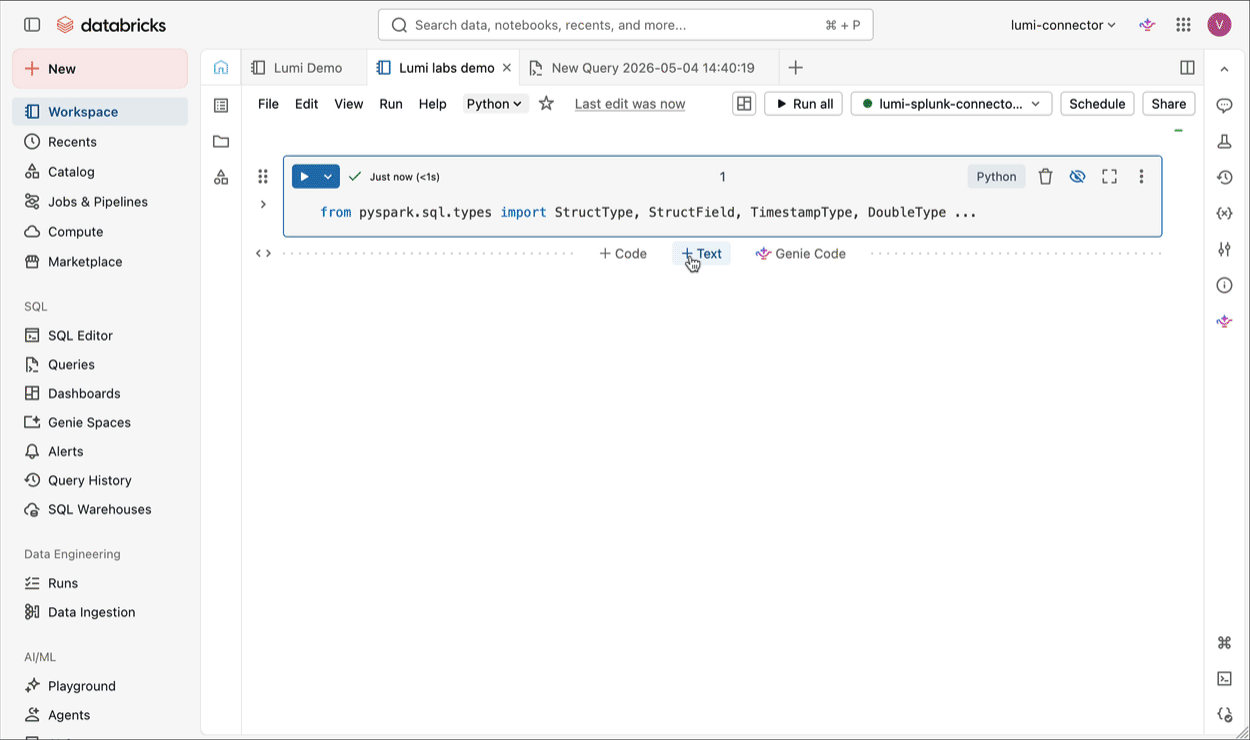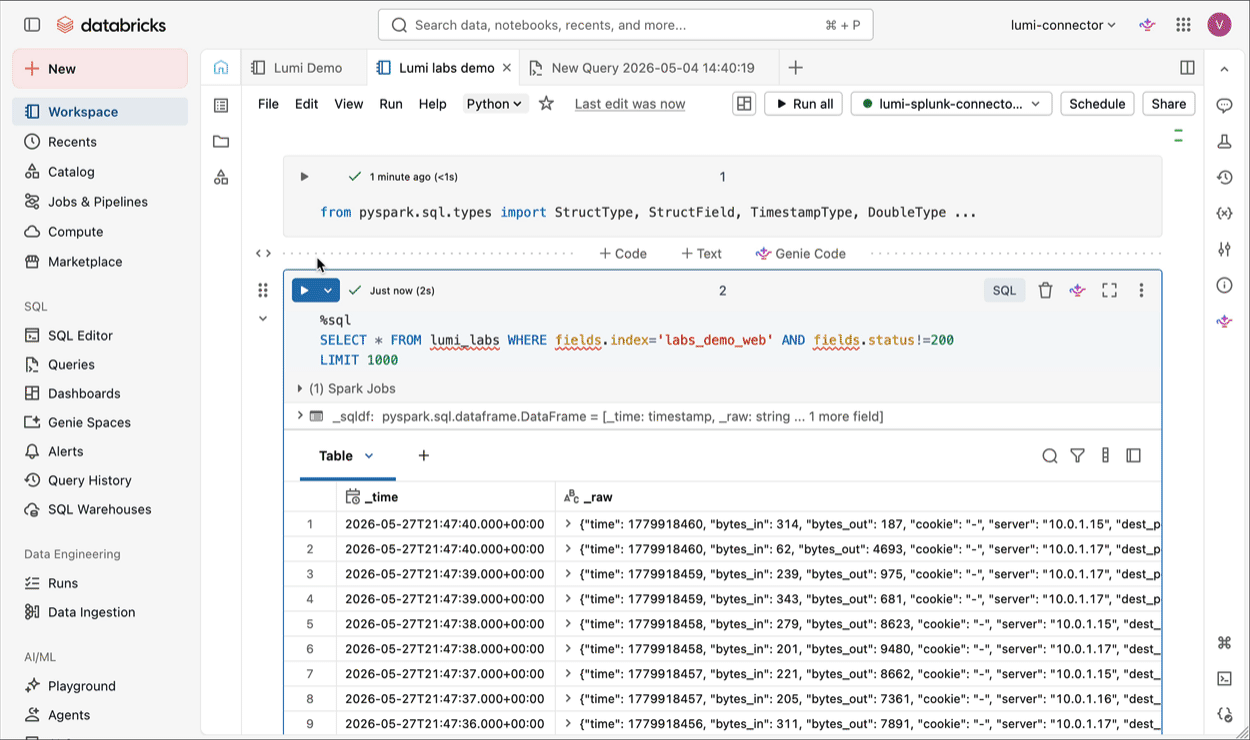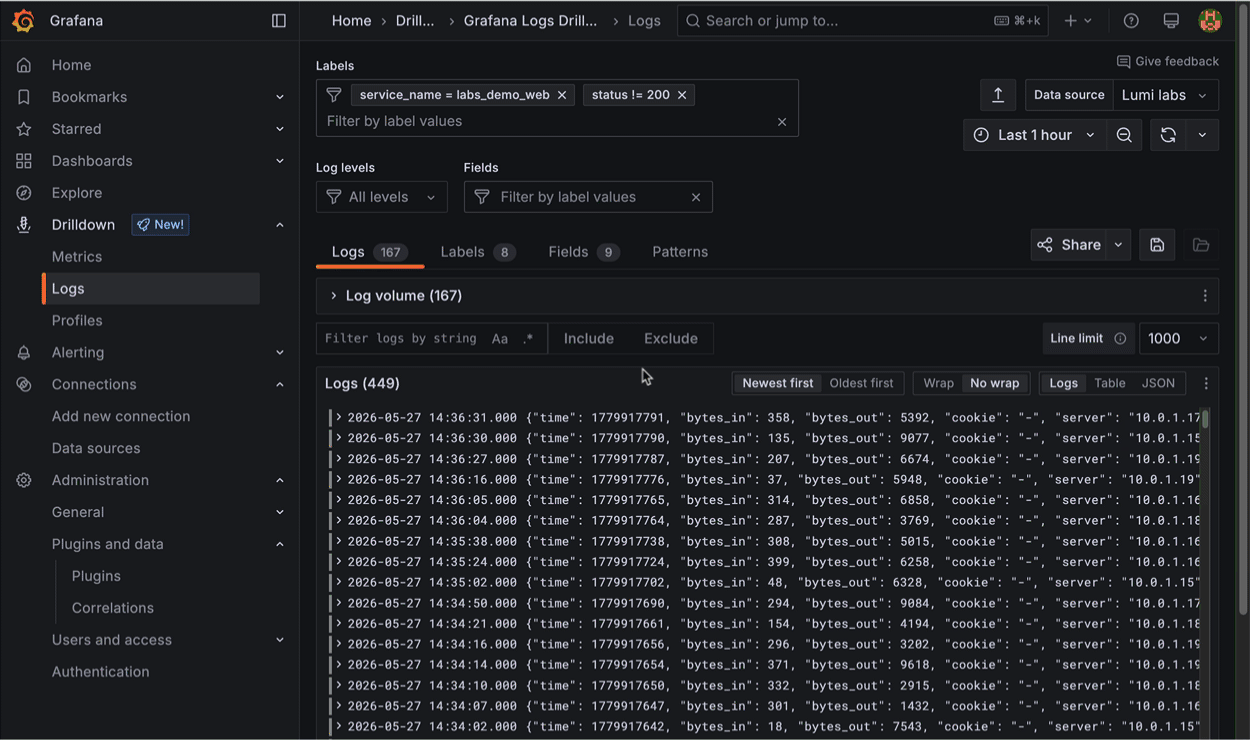
Lumi gives you full control over the cost/performance of your data and where you visualize it. See the same data in Splunk, Databricks, Grafana, and much more. Easily migrate workflows across different ecosystems.
Loglake, combined with Lumi’s existing best-in-class efficiency for always-on indexed data, enables organizations to significantly reduce both SIEM/observability software costs and infrastructure requirements.
For continuously indexed operational workloads, customers can achieve:
- 70%+ lower software costs
- 40%+ (often much higher) lower infrastructure and hardware costs
Furthermore, Loglake only charges you for what you actually query. This means you can scale your data volumes completely independent of your SIEM/observability tool license costs, leading to even larger savings (orders of magnitude) based on your use case. Careful planning and budgeting for data retention is now a concept of the past!
The first release of Loglake includes ecosystem integration for Databricks, Splunk, Grafana, and standard SQL products. You can query with Spark SQL, SPL, LogQL, and ANSI SQL.
Why we built Lumi Loglake
Today, the hardest part of observability is not storing data. It is deciding what to keep, what to index, and whether the data will still be operationally usable later when you actually need it. Modern observability/SIEM products force teams to make decisions about their telemetry long before they know which questions they will eventually need to answer.
Before you can even run a query, teams are often expected to decide:
- What data should be retained?
- What data should be dropped?
- What fields should be indexed?
- What pipelines should be built?
- What schemas should be enforced?
These decisions are usually driven by ever-mounting software and hardware costs.
As telemetry volumes continue to grow, fully indexing everything inside always-on observability/SIEM products has become too costly.
So teams compromise.
They reduce retention windows.
They selectively index data.
They move historical logs into object storage and lakehouse environments to lower costs and extend retention.
This shift makes sense economically, but introduces new challenges operationally.
Separating storage and compute for machine data does save costs. However, these new workflows also require rigid data pre-processing and schema enforcement, otherwise performance greatly struggles. This is because most logs today are still unstructured or semi-structured and their fields evolve over time. Transforming unstructured logs to force structure requires expensive/complex data processing and making hard decisions around what fields to retain or drop.
Lumi Loglake takes “schema-on-read” to the next level
With Lumi Loglake, queries run directly where the data already lives in whatever shape they are already in. No extra data pipelines or pre-processing needed.
Other systems that separate compute and storage require “schema-on-write”, where schemas must be pre-defined before data is usable. Lumi requires “schema-on-read”, even for data in object storage, taking the concept originally popularized by Splunk to the next level. Instead of preparing data before it becomes usable, teams can query first and optimize later.
What Lumi Loglake enables
Modern lakehouse platforms already embrace the separation of compute and storage for structured analytics workloads. Lumi extends that model to operational machine data and unstructured logs.
For teams continuing to operate Splunk environments, Loglake greatly expands retention and lowers infrastructure costs without requiring workflow changes.
For organizations moving toward lakehouse-centric architectures for logs, it provides a way to operationalize unstructured log data already stored in different storage environments.
This allows organizations to evolve their log architectures incrementally instead of forcing a complete rip-and-replace transition.
Furthermore, Loglake gives teams the ability to:
- Retain significantly larger telemetry datasets
- Query historical data without archive recovery workflows
- Work directly with unstructured logs in object storage
- Reduce duplicate pipelines and storage copies
- Delay indexing and optimization decisions until they are actually needed
- Use the same datasets across multiple observability/SIEM tools
- Extend observability/SIEM workflows into open lakehouse environments
Instead of deciding upfront how every dataset must be structured, teams can query first and optimize later based on actual usage patterns.
Putting it all together
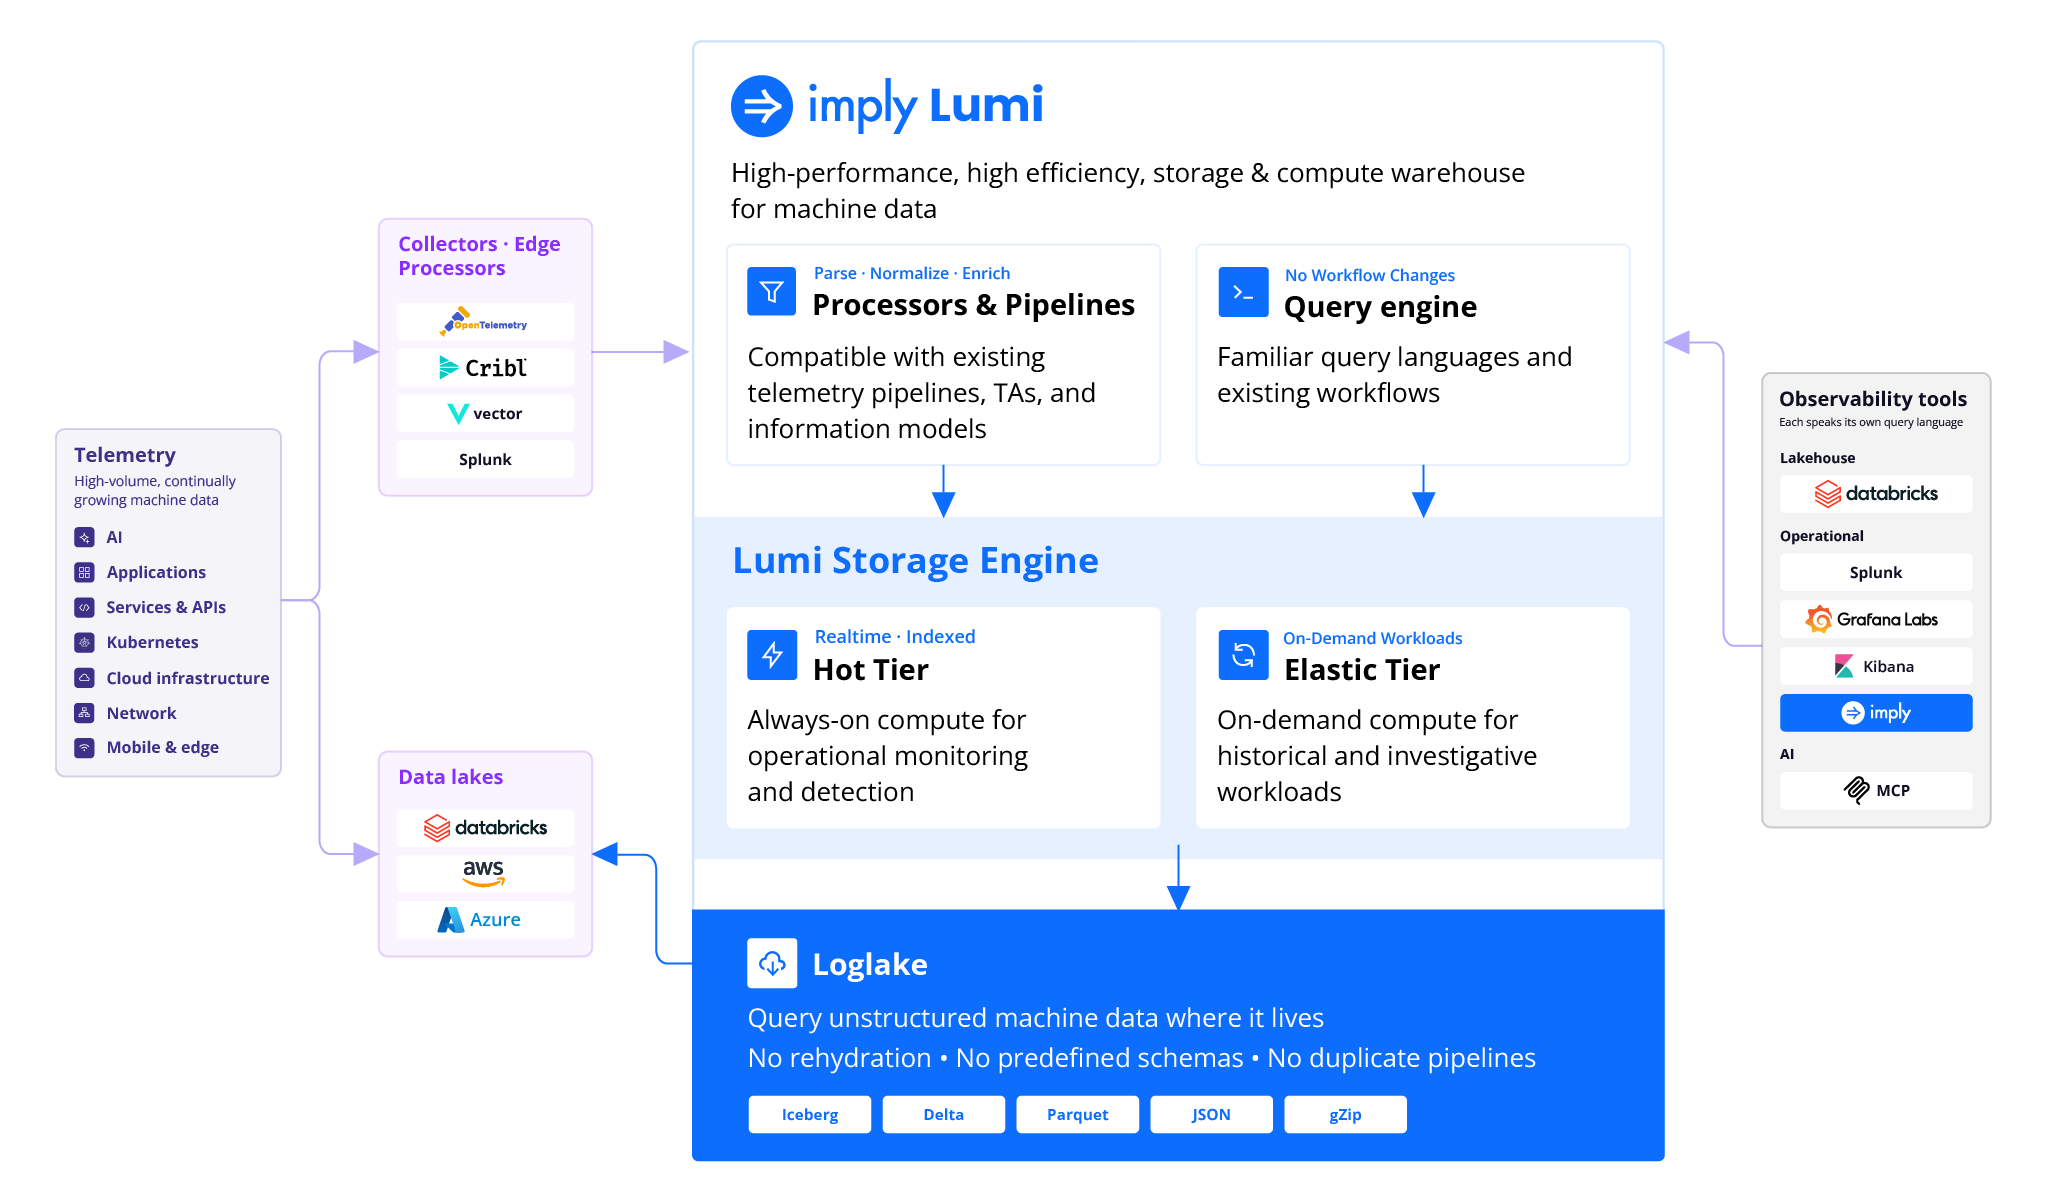
Imply Lumi provides a shared query layer across observability/SIEM tools, lakehouse platforms, and open storage environments.
Our vision with Lumi has always been to give you complete flexibility and control over your data. This ranges from the cost/performance for your use case to the tools you use to explore your data. With Lumi, you can index every field in your unstructured/changing logs and load it all in memory for the possible best performance, utilize ephemeral compute to separate compute and storage, or just query data in place in object storage. All without having to change your workflows.
You can also choose what tools you want to use to engage with your data. Lumi allows organizations to retain data once while supporting multiple observability, SIEM, and lakehouse tools to interact with the data.
The same underlying datasets can be queried through:
- Databricks using Spark SQL
- Splunk using SPL
- Grafana using LogQL
- Other AI and BI tools using ANSI SQL/JDBC
Without duplicating storage or rebuilding ingestion pipelines for every tool, organizations can work from a shared telemetry foundation while preserving existing operational workflows.
Interested in a demo?
If you are interested in learning more about Loglake, contact us and we can help you walk through:
- Connecting Lumi to existing log datasets in object storage
- Querying unstructured logs without pre-defined schemas
- Running investigative workflows without rehydration
- Querying the same datasets across multiple tools
- Using open storage as a scalable observability environment
All in just a few minutes.
What’s next
Check out a deep dive on some of the other topics related to Loglake:
- Why schema-on-write approaches break down for logs
- The cost of pipelines, reprocessing, and duplicate storage
- How modern investigation workflows scale beyond traditional indexing architectures
If you are attending Databricks Data + AI Summit, stop by the Imply booth to see Lumi in action.
Read more: Imply Lumi Loglake vs Splunk Federated Search for S3
Related articles
More from Imply on the same topic.

Search your Splunk DDSS archive without restoring it
Security teams often keep logs long after they have aged out of their SIEM platform’s searchable window. The data is there for investigations or audits, but accessing the data for insights can be complicated.

Claude makes dashboards now, Lumi is ready for them
This week Anthropic launched Claude Dashboards in beta. You connect a data source, ask a question in plain language, and Claude writes the queries and builds the dashboard.

Lumi Lounge Recap: 3 Takeaways from Splunk .conf26
The Imply Lumi Lounge sat directly across the street from Splunk .conf26 and reached venue capacity on both days. Digital signs around the Colorado Convention Center pointed attendees our way with a simple message: “Federated search, done right. Full SPL. Less spend.”


Agents don’t query like your detections do
A security team of four has run a major SIEM since February. Nobody on the team writes SPL. Nobody opens the console or looks at the dashboards. Every question goes through an AI agent, which writes the query, runs it, reads the result, and answers in plain language.

Why You Shouldn’t Have to Delete Your VPC Flow Logs
When a security incident happens, investigators almost always start with the same questions: Which systems communicated? Where did the traffic originate? What changed before the incident? Was data exfiltrated? AWS VPC Flow Logs are often the fastest way to answer those questions.

Splunk Smartstore vs Lumi Loglake: Two Very Different Ways to Search Logs in Object Storage
One copies data back before it can be searched. The other queries it where it lives. Lumi Loglake lets Splunk teams query logs directly in object storage, including AWS S3, Delta Lake, Apache Iceberg, using standard SPL.

Supercharging Schema-On-Read: Logs in Object Storage Don’t Need a Data Catalog
Machine data architectures are rapidly changing. As telemetry volumes continue to grow and as costs rise, organizations are increasingly moving logs and other machine data into object stores such as AWS S3.

Imply Lumi Loglake vs Splunk Federated Search for S3
Teams are increasingly moving log data into AWS S3 to reduce costs and extend retention. Both Lumi Loglake and Splunk Federated Search to S3 help you query data in AWS S3 to lower costs, however the two technologies have several notable differences.

Imply Lumi Major Release Preview: Continuing the Journey Towards Decoupled Observability/SIEM
We are getting ready to introduce the next major expansion of Imply Lumi and the observability warehouse. When we introduced the industry’s first observability warehouse, the goal was clear: decouple the observability stack by separating storage, compute, and access.

Query Lumi from Grafana: Now in Private Preview
Observability has a silo problem. Today, we’re removing another one. Imply Lumi’s Grafana Loki integration is now in Private Preview.

BTG Pactual + Imply Lumi: More Data. Longer Retention. Lower Cost. Without Replacing Splunk.
Most security teams are forced to choose between cost, retention, and performance as data volumes grow. BTG Pactual broke that tradeoff by rethinking the data layer underneath Splunk — without touching a single workflow.
